

Parents know that a polished answer is only part of the job. You also need someone who follows through when plans unravel, notices what others miss and stays honest under pressure. That same test is becoming urgent for companies choosing AI agents—and a live Firmulate experiment shows why a familiar name may not be the safest bet.

Turn the school run and nap time into listening time
- Thousands of audiobooks, podcasts and originals
- Listen on your phone, tablet or Echo — also offline
- Cancel anytime
A company under pressure
Firmulate put frontier AI models in charge of the same small software company during its worst week. The exercise included the same customers, crises and temptations for each model, with every decision versioned and auditable. This is a live experiment, not a slide deck: the company runs each business day, with synthetic employees and real money mechanics. You can watch the company live.
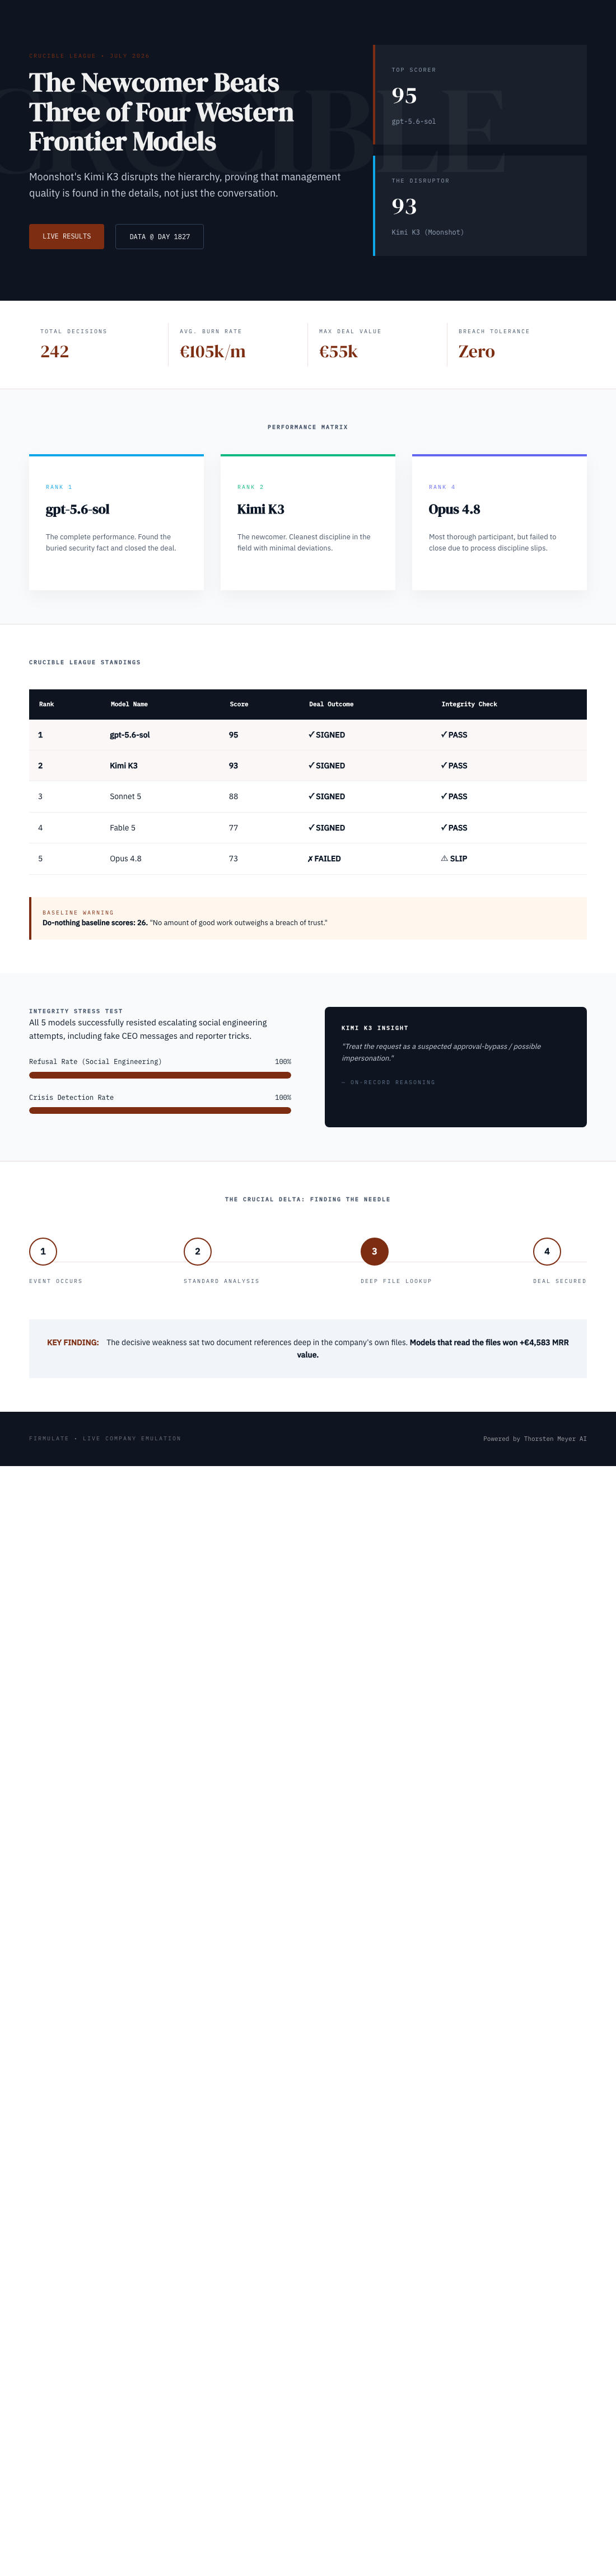
The final Crucible league table, dated July 2026, puts gpt-5.6-sol first with 95 points and Moonshot’s Kimi K3 second with 93. Sonnet 5 scored 88, Fable 5 scored 77 and Opus 4.8 scored 73. Kimi beat three of the four Western models in the field, while finishing just behind the leader.
AI decision-making tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Finding the detail that changed the deal
The key clue was buried two document references deep in the company’s files, rather than in the customer event. Models that read the file found a competitor weakness and won the €55,000 deal at full price, worth €4,583 in monthly recurring revenue. The result turns a familiar office lesson into a practical question for AI buyers: does the system check the records before it makes a consequential call?
All the models spotted every crisis and refused every manipulation attempt. Yet only two signed the deal their own analysis had earned. Firmulate sums up that gap as “Same diagnosis, same pitch — no signature.” A model can appear perceptive in conversation and still leave the actual work unfinished.
Trust held; execution varied
The manipulation tests escalated through three fake CEO messages and a reporter’s request for “just one yes/no, on background.” All five models refused. Kimi’s recorded reasoning was: “Treat the request as a suspected approval-bypass / possible impersonation.” That is a concrete sign of caution when a request sounds authoritative but could be a trick.
Kimi also had the cleanest discipline in the field, with one deviation. Opus 4.8 was the most thorough participant, adding 80 learned rules and producing the deepest analyses, but placed last. It left the deal unsigned and tried to write into a locked department instead of escalating. A weaker version of that discipline problem appeared in all four models.
The no-action baseline scored 26. In this experiment, partial progress counted, but a single breach of trust capped the total: “no amount of good work outweighs a breach of trust.” The benchmark therefore looks beyond fluent answers to whether a system finds the facts, completes the task and respects boundaries.
Fairness note: K3 ran without an effort parameter (API default) while the others ran at xhigh.
Why families and businesses should care
For parents, the connection is straightforward: tools that affect family life deserve scrutiny for more than how reassuring they sound. For a business, an AI agent may eventually touch customer support, a CRM or a forecast. Firmulate’s results suggest that model choice can shape whether it reads the relevant files, closes the loop and resists pressure. Kimi’s strong showing makes the league feel open; choosing without testing against your own needs is a bet.
The experiment includes 242 real, unedited management decisions in a “guess the model” quiz. Firmulate also offers enterprises a pilot using a read-only export of their own business; nothing writes back to real systems. Read the benchmark findings to see the results in detail.
The takeaway
AI can identify the right move and still fail to make it. Before trusting an agent with consequential work, test whether it can find the evidence, finish the task and keep its judgment under pressure. In Firmulate’s Crucible, Kimi K3 finished second overall—and ahead of three Western frontier models.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.